切片类型
切片让你可以引用集合中连续的一段元素。切片是一种引用,因此它不拥有数据。
来看一个小编程题:编写一个函数,接收一串由空格分隔的单词,并返回找到的第一个单词。如果字符串中没有空格,那么整个字符串就是一个单词,应当返回整个字符串。
注意:为了介绍切片,本节仅假设使用 ASCII 字符;关于 UTF-8 处理的更完整讨论,请参阅第 8 章“使用字符串存储 UTF-8 编码文本”一节。
让我们先看看不使用切片时该如何编写函数签名,从而理解切片要解决的问题:
fn first_word(s: &String) -> ?first_word 函数的参数类型是 &String。我们不需要取得所有权,因此这样做没问题。(按照 Rust 的惯用风格,除非确有需要,函数不会取得参数的所有权。随着后续学习,这么做的原因会逐渐明朗。)但我们应该返回什么呢?我们还没有办法表示字符串的一部分。不过,可以返回单词末尾的索引,也就是空格所在的位置。试着这样做,如代码清单 4-7 所示。
fn first_word(s: &String) -> usize {
    let bytes = s.as_bytes();

    for (i, &item) in bytes.iter().enumerate() {
        if item == b' ' {
            return i;
        }
    }

    s.len()
}

fn main() {}first_word 函数返回 String 参数中的字节索引由于我们需要逐个遍历 String 中的元素,检查某个值是否为空格,因此要使用 as_bytes 方法将 String 转换为字节数组。
fn first_word(s: &String) -> usize {
    let bytes = s.as_bytes();

    for (i, &item) in bytes.iter().enumerate() {
        if item == b' ' {
            return i;
        }
    }

    s.len()
}

fn main() {}
接下来,我们使用 iter 方法为字节数组创建迭代器:
fn first_word(s: &String) -> usize {
    let bytes = s.as_bytes();

    for (i, &item) in bytes.iter().enumerate() {
        if item == b' ' {
            return i;
        }
    }

    s.len()
}

fn main() {}我们会在第 13 章更详细地讨论迭代器。目前只需知道,iter 方法会返回集合中的每个元素,而 enumerate 会包装 iter 的结果,将每个元素作为元组的一部分返回。enumerate 返回的元组中,第一个元素是索引,第二个元素是对该元素的引用。这比我们自己计算索引方便一些。
由于 enumerate 方法返回元组,我们可以使用模式来解构元组。我们会在第 6 章进一步讨论模式。在 for 循环中,我们指定一个模式:用 i 表示元组中的索引,用 &item 表示元组中的单个字节。由于 .iter().enumerate() 返回的是元素引用,因此模式中要使用 &。
在 for 循环内部,我们使用字节字面量语法查找表示空格的字节。如果找到空格,就返回它的位置;否则,使用 s.len() 返回字符串长度。
fn first_word(s: &String) -> usize {
    let bytes = s.as_bytes();

    for (i, &item) in bytes.iter().enumerate() {
        if item == b' ' {
            return i;
        }
    }

    s.len()
}

fn main() {}
现在我们有办法找到字符串中第一个单词末尾的索引了,但这还存在一个问题。我们单独返回了一个 usize,但只有结合 &String 时它才有意义。换句话说,由于它是与 String 分离的独立值,我们无法保证它今后仍然有效。看看代码清单 4-8 中使用代码清单 4-7 的 first_word 函数的程序。
fn first_word(s: &String) -> usize {
    let bytes = s.as_bytes();

    for (i, &item) in bytes.iter().enumerate() {
        if item == b' ' {
            return i;
        }
    }

    s.len()
}

fn main() {
    let mut s = String::from("hello world");

    let word = first_word(&s); // word will get the value 5

    s.clear(); // this empties the String, making it equal to ""

    // word still has the value 5 here, but s no longer has any content that we
    // could meaningfully use with the value 5, so word is now totally invalid!
}first_word 函数的结果,然后修改 String 的内容这个程序可以成功编译;即使我们在调用 s.clear() 后使用 word,它也能编译。由于 word 与 s 的状态完全没有关联,它仍然保存着值 5。我们可以尝试使用值 5 和变量 s 提取第一个单词,但这会导致 bug,因为自从我们将 5 存入 word 后,s 的内容已经改变。
还要担心 word 中的索引与 s 中的数据不同步,既麻烦又容易出错!如果再编写一个 second_word 函数来管理这些索引,情况会更加脆弱。它的签名必须像这样:
fn second_word(s: &String) -> (usize, usize) {现在我们要追踪起始和结束索引,产生了更多根据特定状态的数据计算出来、却与该状态完全没有关联的值。于是我们有三个互不相关、却需要保持同步的变量。
幸运的是,Rust 有一个解决方案:字符串切片。
字符串切片
字符串切片是对 String 中连续一段元素的引用,如下所示:
fn main() {
    let s = String::from("hello world");

    let hello = &s[0..5];
    let world = &s[6..11];
}与引用整个 String 不同,hello 引用的是 String 的一部分,由额外的 [0..5] 指定。我们可以在方括号中使用范围来创建切片,格式为 [starting_index..ending_index]。其中,starting_index 是切片中的第一个位置,ending_index 则比切片中最后一个位置大 1。在内部,切片数据结构会存储起始位置和切片长度;长度等于 ending_index 减去 starting_index。因此,对于 let world = &s[6..11];,world 是一个切片,包含指向 s 中索引 6 处字节的指针,长度值为 5。
图 4-7 用示意图展示了这一点。
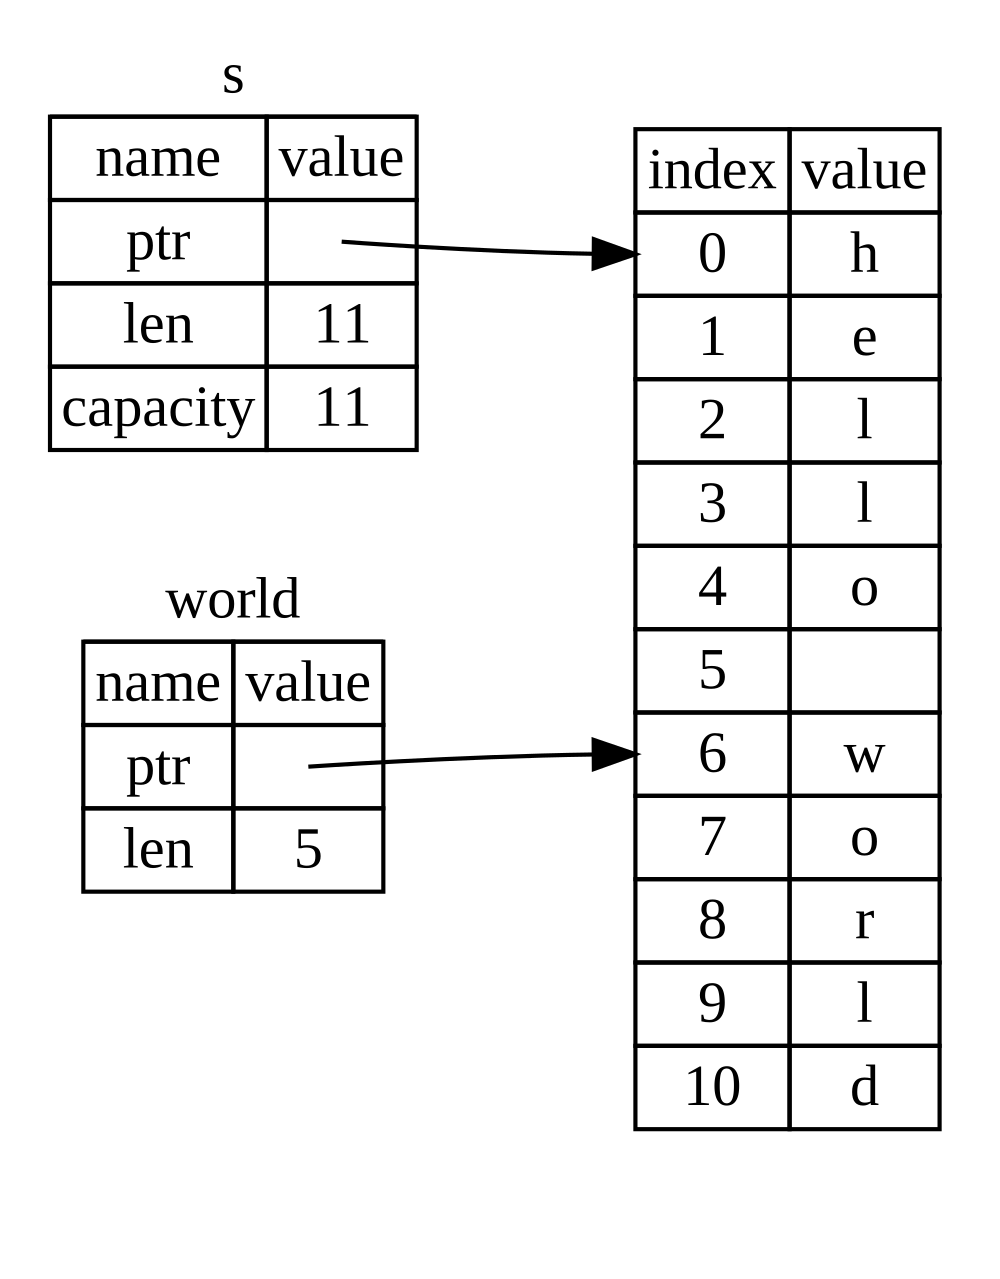
图 4-7:引用 String 一部分内容的字符串切片
使用 Rust 的 .. 范围语法时,如果要从索引 0 开始,可以省略两个点前面的值。换句话说,下面两种写法相同:
#![allow(unused)]
fn main() {
let s = String::from("hello");

let slice = &s[0..2];
let slice = &s[..2];
}
同理,如果切片包含 String 的最后一个字节,就可以省略末尾的数字。也就是说,下面两种写法相同:
#![allow(unused)]
fn main() {
let s = String::from("hello");

let len = s.len();

let slice = &s[3..len];
let slice = &s[3..];
}
你也可以省略两个值,从而获取整个字符串的切片。因此,下面两种写法相同:
#![allow(unused)]
fn main() {
let s = String::from("hello");

let len = s.len();

let slice = &s[0..len];
let slice = &s[..];
}
注意:字符串切片的范围索引必须位于有效的 UTF-8 字符边界。如果尝试在多字节字符的中间创建字符串切片,程序就会报错并退出。
了解这些信息后,让我们重写 first_word,使它返回切片。表示“字符串切片”的类型写作 &str:
fn first_word(s: &String) -> &str {
    let bytes = s.as_bytes();

    for (i, &item) in bytes.iter().enumerate() {
        if item == b' ' {
            return &s[0..i];
        }
    }

    &s[..]
}

fn main() {}
我们像代码清单 4-7 中那样,通过查找第一个空格来获取单词末尾的索引。找到空格后,我们以字符串开头和空格索引作为起止位置,返回一个字符串切片。
现在调用 first_word 时,我们会得到一个与底层数据关联的单一值。这个值由指向切片起始位置的引用以及切片中元素的数量组成。
让 second_word 函数返回切片也同样可行:
fn second_word(s: &String) -> &str {现在我们有了一个简单直接、不容易出错的 API,因为编译器会确保指向 String 的引用始终有效。还记得代码清单 4-8 中的 bug 吗?我们获得第一个单词末尾的索引后清空了字符串,导致索引失效。那段代码在逻辑上有误,却不会立即报错。如果继续使用空字符串和第一个单词的索引,问题才会显现。切片让这个 bug 不可能发生,并能更早提醒我们代码存在问题。使用返回切片的 first_word 版本会触发编译时错误:
fn first_word(s: &String) -> &str {
    let bytes = s.as_bytes();

    for (i, &item) in bytes.iter().enumerate() {
        if item == b' ' {
            return &s[0..i];
        }
    }

    &s[..]
}

fn main() {
    let mut s = String::from("hello world");

    let word = first_word(&s);

    s.clear(); // error!

    println!("the first word is: {word}");
}
编译器错误如下:
$ cargo run
   Compiling ownership v0.1.0 (file:///projects/ownership)
error[E0502]: cannot borrow `s` as mutable because it is also borrowed as immutable
  --> src/main.rs:18:5
   |
16 |     let word = first_word(&s);
   |                           -- immutable borrow occurs here
17 |
18 |     s.clear(); // error!
   |     ^^^^^^^^^ mutable borrow occurs here
19 |
20 |     println!("the first word is: {word}");
   |                                   ---- immutable borrow later used here

For more information about this error, try `rustc --explain E0502`.
error: could not compile `ownership` (bin "ownership") due to 1 previous error
还记得借用规则吗:如果我们持有某个值的不可变引用,就不能再创建可变引用。由于 clear 需要截断 String,它需要获取可变引用。调用 clear 之后的 println! 还会使用 word 中的引用,因此此时不可变引用仍然有效。Rust 不允许 clear 中的可变引用和 word 中的不可变引用同时存在,因此编译失败。Rust 不仅让我们的 API 更容易使用,还在编译时消除了一整类错误!
字符串字面量就是切片
还记得我们提到过字符串字面量存储在二进制文件中吗?了解切片后,我们就能正确理解字符串字面量了:
#![allow(unused)]
fn main() {
let s = "Hello, world!";
}
这里 s 的类型是 &str:它是一个指向二进制文件中特定位置的切片。这也解释了字符串字面量为何不可变:&str 是不可变引用。
将字符串切片用作参数
既然字符串字面量和 String 值都可以创建切片,我们就可以进一步改进 first_word,改进它的函数签名:
fn first_word(s: &String) -> &str {经验更丰富的 Rustacean 会像代码清单 4-9 那样编写签名,因为这样同一个函数既可以处理 &String 值,也可以处理 &str 值。
fn first_word(s: &str) -> &str {
    let bytes = s.as_bytes();

    for (i, &item) in bytes.iter().enumerate() {
        if item == b' ' {
            return &s[0..i];
        }
    }

    &s[..]
}

fn main() {
    let my_string = String::from("hello world");

    // `first_word` works on slices of `String`s, whether partial or whole.
    let word = first_word(&my_string[0..6]);
    let word = first_word(&my_string[..]);
    // `first_word` also works on references to `String`s, which are equivalent
    // to whole slices of `String`s.
    let word = first_word(&my_string);

    let my_string_literal = "hello world";

    // `first_word` works on slices of string literals, whether partial or
    // whole.
    let word = first_word(&my_string_literal[0..6]);
    let word = first_word(&my_string_literal[..]);

    // Because string literals *are* string slices already,
    // this works too, without the slice syntax!
    let word = first_word(my_string_literal);
}s 参数的类型改为字符串切片,以改进 first_word 函数如果有字符串切片,可以直接传入。如果有 String,可以传入它的切片或对它的引用。这种灵活性利用了解引用强制转换功能,我们会在第 15 章“在函数和方法中使用解引用强制转换”一节介绍。
将函数参数定义为字符串切片,而不是 String 的引用,可以在不损失任何功能的前提下,让 API 更通用、更实用:
fn first_word(s: &str) -> &str {
    let bytes = s.as_bytes();

    for (i, &item) in bytes.iter().enumerate() {
        if item == b' ' {
            return &s[0..i];
        }
    }

    &s[..]
}

fn main() {
    let my_string = String::from("hello world");

    // `first_word` works on slices of `String`s, whether partial or whole.
    let word = first_word(&my_string[0..6]);
    let word = first_word(&my_string[..]);
    // `first_word` also works on references to `String`s, which are equivalent
    // to whole slices of `String`s.
    let word = first_word(&my_string);

    let my_string_literal = "hello world";

    // `first_word` works on slices of string literals, whether partial or
    // whole.
    let word = first_word(&my_string_literal[0..6]);
    let word = first_word(&my_string_literal[..]);

    // Because string literals *are* string slices already,
    // this works too, without the slice syntax!
    let word = first_word(my_string_literal);
}
其他切片
顾名思义,字符串切片专用于字符串。不过还有一种更通用的切片类型。来看这个数组:
#![allow(unused)]
fn main() {
let a = [1, 2, 3, 4, 5];
}
正如我们可能想引用字符串的一部分,我们也可能想引用数组的一部分。可以这样做:
#![allow(unused)]
fn main() {
let a = [1, 2, 3, 4, 5];

let slice = &a[1..3];

assert_eq!(slice, &[2, 3]);
}
这个切片的类型是 &[i32]。它与字符串切片的工作方式相同:存储对第一个元素的引用以及长度。你会在各种其他集合中使用这种切片。我们会在第 8 章讨论向量时详细介绍这些集合。
总结
所有权、借用和切片这些概念可以在编译时确保 Rust 程序的内存安全。Rust 语言像其他系统编程语言一样,让你能够控制内存使用方式。但数据所有者离开作用域时会自动清理数据,因此你无需编写和调试额外代码就能实现这种控制。
所有权会影响 Rust 中许多其他部分的工作方式,因此本书后续还会继续讨论这些概念。现在进入第 5 章,看看如何使用 struct 将数据组合在一起。